Secure File Uploads for SaaS: Storage, Limits and Costs
Secure file uploads for SaaS: where to store files, how to sign uploads, what limits to set, and how to keep storage costs predictable.
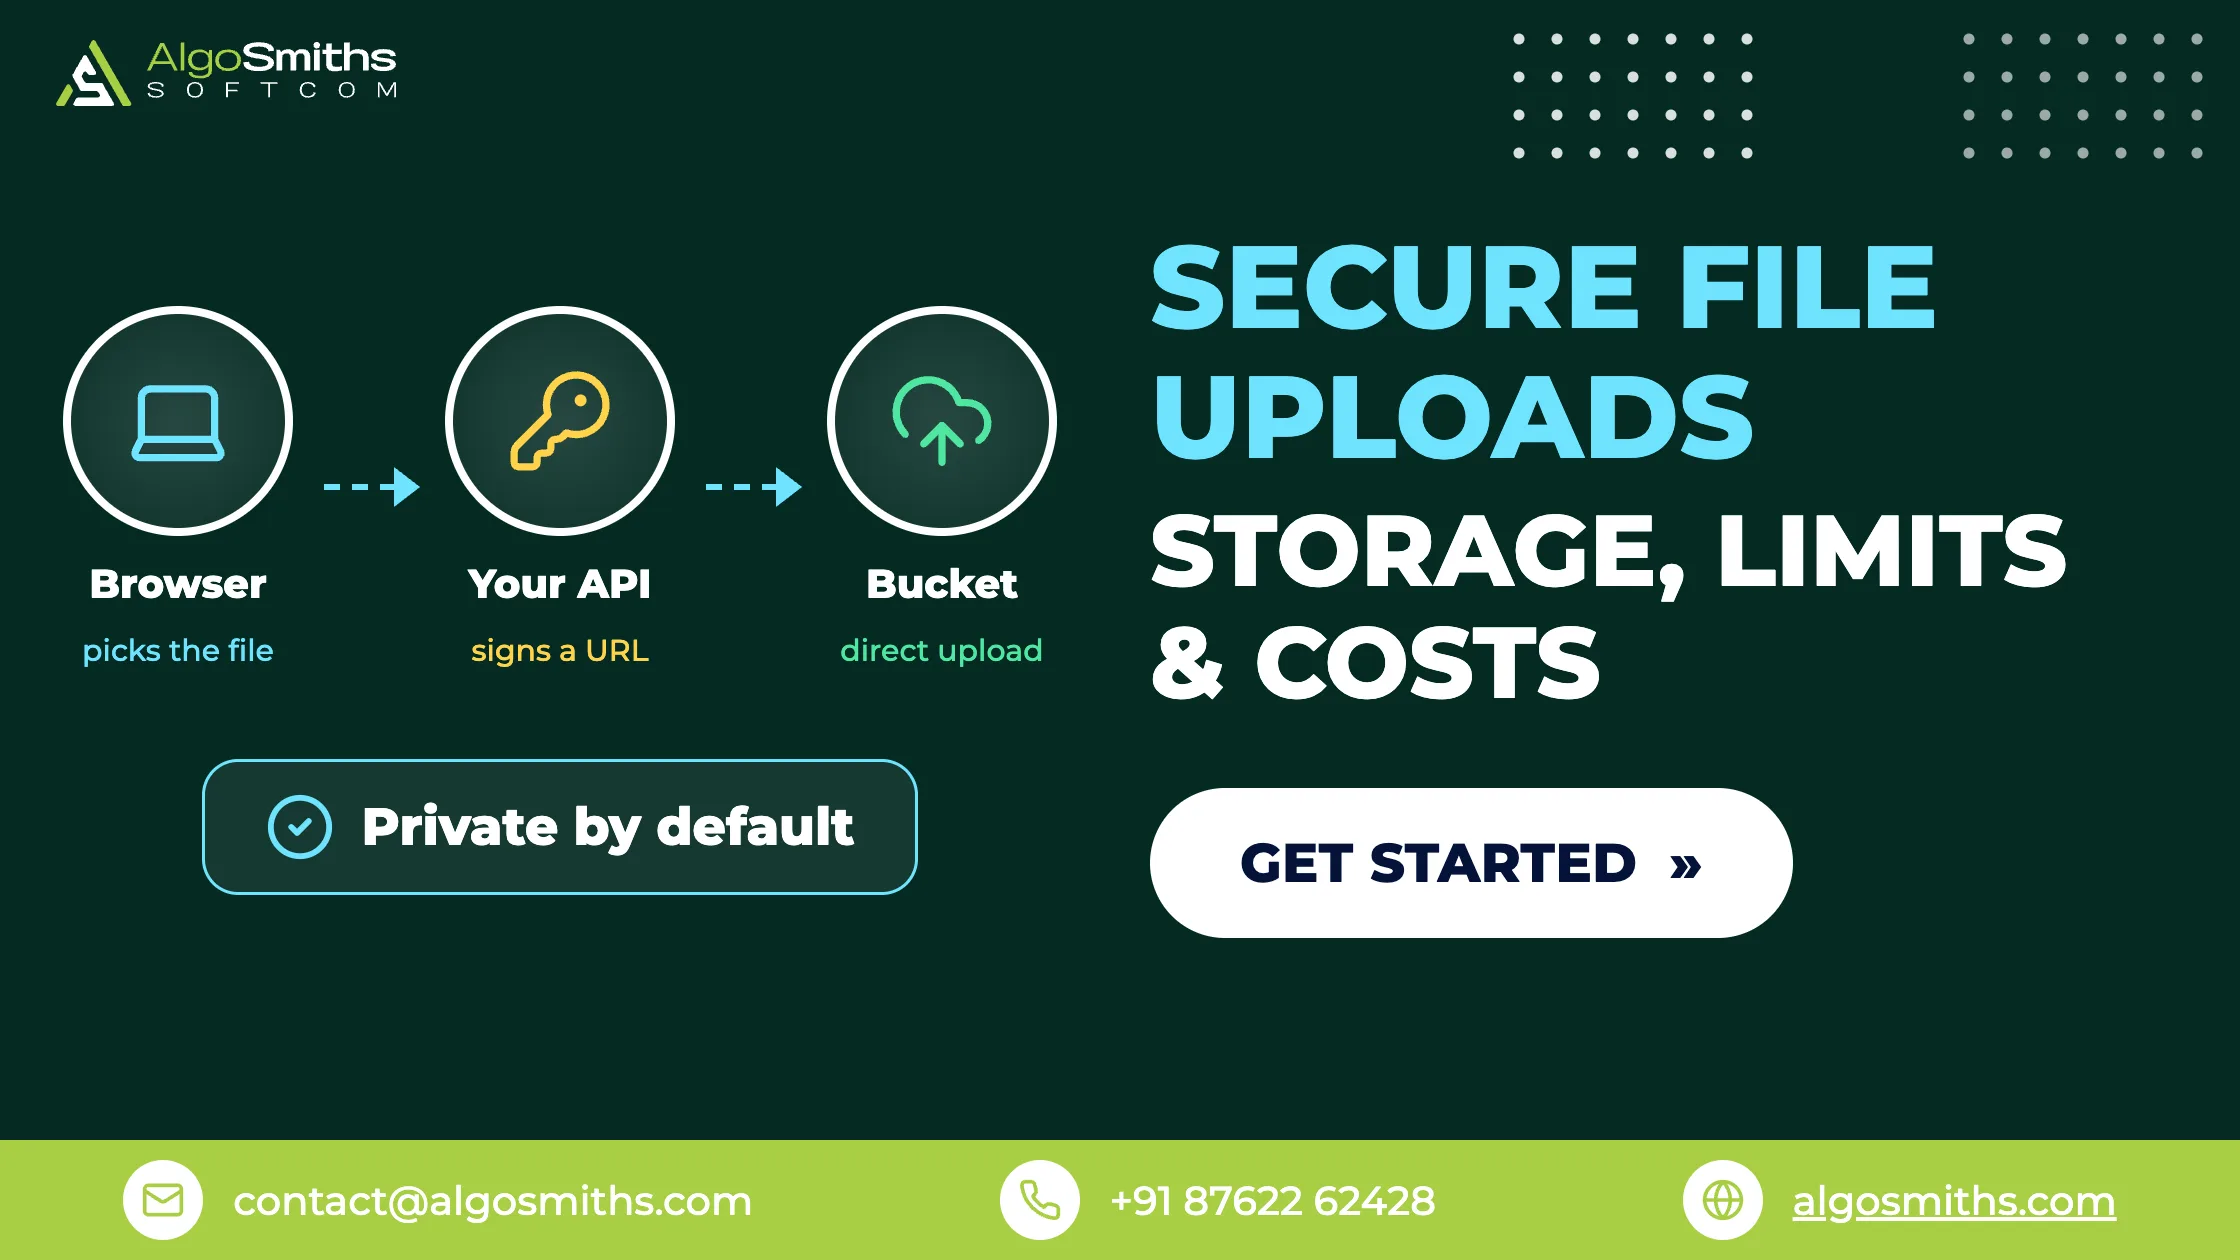
Store user-uploaded files in object storage, not in your database and not on the server's disk, and let the browser send them straight there using a short-lived signed URL that your backend issues. Secure file uploads then come down to four decisions: where the bytes live, who is allowed to read them, what you accept, and what happens after an upload lands.
This guide is for founders and small teams adding profile photos, documents, CSV imports or video to a SaaS product, and for anyone whose prototype currently writes files somewhere that will not survive real users. It covers the storage choice, direct browser uploads, access control, validation, cost and the work that should happen in the background. If your app runs on Supabase, our walkthrough of finding and fixing row-level security gaps covers the database half of the same problem.
Key takeaways
- Object storage is the default home for files. Your database stores a row describing the file, never the file itself.
- Upload direct from the browser with a presigned URL, so large files never pass through your application server.
- Keep every bucket private and serve files through short-lived signed download URLs or your own handler. An unguessable public URL is not access control.
- Validate the file by its signature, rename it server-side and cap the size per bucket. The browser's
Content-Typeheader is user input. - Egress, not storage, is what moves the bill. Price downloads before you ship anything image- or video-heavy.
Where should user-uploaded files live?
In a private object storage bucket, with a row in your database recording what was uploaded, by whom, and where it sits. Object storage is built for exactly this: cheap bytes, unlimited count, no schema.
The two tempting alternatives both cause problems within months. Storing files in the database as binary columns inflates every backup and turns a five-minute restore into an hour. Storing them on the server's disk works until the first redeploy wipes the container, or until you run a second instance and half your users get a broken image depending on which machine answers.
A workable files table holds the owner, the storage key, the declared and verified type, the byte size, a checksum and a status. Status matters more than it looks, because an upload can start and never finish.
The three options most startups choose
Almost every early-stage product lands on one of these, and the right answer usually follows whatever the rest of the stack already uses.
| Option | Best for | Egress | Access control | Main trade-off |
|---|---|---|---|---|
| Amazon S3 | Teams already on AWS | Charged per GB | IAM policies plus presigned URLs | Most pieces to configure |
| Cloudflare R2 | Download-heavy products | Free | API tokens plus signed URLs | Smaller tooling ecosystem |
| Supabase Storage | Apps already on Supabase | Counted against an allowance | Policies tied to the same auth users | Coupled to the Supabase project |
All three speak roughly the same API, so the decision is reversible. Moving a few hundred gigabytes between providers is a weekend of copying, not a rewrite, as long as your code asks a storage module for a URL rather than building provider URLs by hand.
How do you upload files without routing them through your server?
You ask your backend for a presigned URL — a temporary, signed address that authorises one specific upload — and the browser sends the file to storage directly. Your server handles a small JSON request instead of the file.
This matters because application servers are bad at holding large bodies. A 200 MB upload on a slow connection occupies a worker for minutes, and most hosting platforms cut the request off long before that. Direct uploads remove the problem rather than tuning around it.
The backend decides the storage key, which is the security-relevant part. The client never chooses the path:
import { S3Client, PutObjectCommand } from "@aws-sdk/client-s3";
import { getSignedUrl } from "@aws-sdk/s3-request-presigner";
import { randomUUID } from "node:crypto";

const s3 = new S3Client({ region: "us-east-1" });

export async function createUploadUrl(userId, contentType) {
  const key = `users/${userId}/${randomUUID()}`;

  const command = new PutObjectCommand({
    Bucket: "app-user-uploads",
    Key: key,
    ContentType: contentType,
  });

  const url = await getSignedUrl(s3, command, { expiresIn: 300 });
  return { url, key };
}
How long should an upload URL last?
Minutes, not days. Amazon's documentation sets the ceiling at 12 hours from the S3 console and up to 7 days from the CLI or SDKs with Signature Version 4, while a URL signed with temporary role credentials dies when that session does, whatever expiry you asked for (AWS presigned URL documentation).
Short expiry is not paranoia. AWS describes presigned URLs as bearer tokens: whoever holds one can use it until it expires. Five minutes is plenty for an upload URL and a minute or two is plenty for a download. Keep them out of your logs, out of analytics events and out of anything that renders a URL into a page a third party can read.
Confirming the upload actually happened
Write the database row as pending when you issue the URL, and only mark it ready once storage confirms the object exists, either through a bucket event notification or a HEAD request from your backend. Browsers close tabs and mobile connections drop between the signature and the final byte.
Then sweep. Rows still pending after a day are abandoned uploads, and objects with no matching row are files you are paying to keep for nobody. A weekly job that reconciles the two sides prevents the slow drift that makes storage bills unexplainable a year later.
How do you stop users seeing each other's files?
Make every bucket private, check ownership in your backend on each request, and hand back a signed URL that expires. The file's address should never be something a user can bookmark forever or pass to someone else permanently.
The common shortcut is a public bucket with long random filenames. That is obscurity, not access control. Those URLs end up in shared screenshots, in support tickets, in referrer headers and occasionally in search results, and once one leaks there is no way to revoke it short of moving the file.
Two habits make this easier to get right. Keep identifying information out of storage keys, since an invoice path containing a customer name leaks in every log line it touches. And enforce ownership in one place — a single function that takes a user and a file row and either returns a signed URL or raises — rather than repeating the check in every endpoint that happens to serve a file.
What should you check on every upload?
Allow a specific list of extensions, verify the file's actual signature, rename it yourself and cap the size. OWASP's file upload cheat sheet is blunt about why: the Content-Type header comes from the user and is trivial to spoof, so it is a convenience check and nothing more.
Extension filtering also has well-documented bypasses, including double extensions such as .jpg.php, null bytes such as .php%00.jpg, and case changes such as .pHp. Those tricks only pay off if the stored name influences how the file is later served, which is the strongest argument for generating the stored filename yourself and serving everything through storage rather than from inside your web root.
Limits worth setting on day one
- A size cap per bucket, set at the smallest number your feature can live with. Avatars do not need 500 MB.
- An allowlist of content types on the bucket itself, so a misconfigured client cannot bypass the API check.
- A per-user quota, counted from your files table, so one account cannot fill the bucket.
- A rate limit on URL issuance, because a script that requests ten thousand upload URLs costs you money even if it never uploads anything.
Platform defaults do some of this for you, and they vary by plan. Supabase caps a single file at 50 MB on the free plan and allows up to 500 GB on Pro, per its published pricing, so a prototype that works on a developer's laptop can still reject a customer's video on launch day. Uploads are one line item on a longer list; our pre-launch checklist for AI-built apps covers the rest.
What does file storage actually cost?
Storing the files is close to free. Serving them is where the money goes, and the difference between providers is almost entirely about egress — the charge for data leaving the provider's network.
| Service | Storage per GB-month | Egress to the internet | Included each month |
|---|---|---|---|
| Amazon S3 Standard (N. Virginia) | $0.023 | $0.09 per GB, first 10 TB | 100 GB egress, across all AWS services |
| Cloudflare R2 Standard | $0.015 | No charge | 10 GB storage |
| Supabase Storage (Pro, $25/month) | $0.0213 above the allowance | $0.03 per GB above the allowance | 100 GB storage, 250 GB cached egress |
Those rates come from Amazon's S3 pricing page, Cloudflare's R2 pricing page and Supabase's pricing page. R2 also bills per operation, at $4.50 per million writes and $0.36 per million reads, which is usually a rounding error next to egress but worth knowing if your app lists buckets on every page load.
A worked example makes the shape clear. Five thousand users with a 2 MB avatar each is 10 GB, which costs about 23 cents a month to store on S3. If each of those images is fetched fifty times a month, that is 500 GB leaving the bucket: roughly $36 a month on S3 after the free 100 GB, and nothing at all on R2. Storage grew by cents; the bill grew by two orders of magnitude.
Two fixes do most of the work regardless of provider. Put a CDN in front of the bucket with long cache lifetimes, so repeat views are served from cache rather than from storage. And generate properly sized derivatives instead of shipping the original to a 48-pixel avatar slot.
What happens after the upload?
Anything slow belongs in a background job, not in the request that returns the URL. Thumbnail generation, video transcoding, PDF text extraction and virus scanning all take seconds to minutes, which is far too long to make a user wait and far too fragile to retry inside an HTTP request.
The pattern is the same for all of them: the upload completes, your backend enqueues a job keyed to the file row, and the interface shows a processing state until the job writes its result back. Our guide to handing slow work to a task queue covers the retry and idempotency details that decide whether this is reliable or merely usually fine.
Three jobs earn their place early. Derivatives, so the browser downloads a 20 KB thumbnail instead of a 4 MB photo. Metadata stripping, because phone photos carry GPS coordinates that your users did not mean to publish. And re-encoding images through a current, sandboxed library, which removes most embedded surprises as a side effect of producing a clean output file.
Virus scanning is worth adding the moment one user can download a file another user uploaded. If files only ever return to the person who uploaded them, it is lower priority.
Common mistakes with SaaS file uploads
- Writing to the application server's disk. The next deploy deletes the files, and a second instance splits them.
- Public buckets with unguessable names. Once a URL leaks it cannot be taken back.
- Trusting the filename and content type the browser sent. Both are attacker-controlled strings.
- Letting the client pick the storage key. Generate it on the server, under that user's own prefix.
- Never reconciling storage against the database. Orphaned objects are invisible until the invoice arrives.
Frequently asked questions
Should I ever store files in my database?
Only for small, rare items such as a generated signature image or a tiny icon, where the convenience of one transaction outweighs the cost. Anything users upload in volume should be in object storage, because binary columns slow every backup, every restore and every replica you add later.
Is Cloudflare R2 cheaper than S3?
For download-heavy products, usually yes, because R2 publishes a lower storage rate and does not charge for egress at all. For products that store a lot and serve a little, the gap narrows to the storage rate alone, and S3's deeper integration with the rest of AWS can be worth more than the difference.
Do I need virus scanning on user uploads?
You need it when uploaded files are downloaded by someone other than the uploader, which includes shared workspaces, marketplaces and support attachments. OWASP recommends running files through an antivirus or sandbox where one is available, alongside type validation rather than instead of it.
How do I handle very large files?
Use the provider's multipart or resumable upload rather than a single request. The file is split into parts that upload independently and retry individually, so a dropped connection costs one part instead of the whole transfer — which is the difference between a video feature that works on hotel wifi and one that does not.
Getting uploads right the first time
The decisions that are expensive to reverse are the first two: private object storage with a database row describing each file, and direct browser uploads through short-lived signed URLs. Validation, limits, background processing and CDN caching all layer on top of that without changing it. Get the foundation wrong and every one of them has to be redone.
If you would rather have senior engineers build this into your product, AlgoSmiths works on fixed-price projects with a working demo every week, and finishes with production access, runbooks and a handover call. Our backend and API engineering work is where uploads, storage and the services around them get built.